
Proving Kafka Pipelines with the Confluent CLI: Publish and Subscribe
Description: Validate Kafka pipelines with console producer and consumer tools before writing application code.
- kafka
- confluent
- streaming
- cli
I architect and build data platforms and AI products businesses depend on:
real-time / batch pipelines - analytics - streaming - applied AI - data migration - warehousing - agentic workflows

Description: Validate Kafka pipelines with console producer and consumer tools before writing application code.

Description: Automated weekly rental price retraining with MLflow orchestration, W&B artifact tracking, and Hydra configs.

Description: Spark ETL on EMR in practice — S3 inputs, star-schema outputs, and deploy paths via console, CLI, and Boto3.
2026-08-31
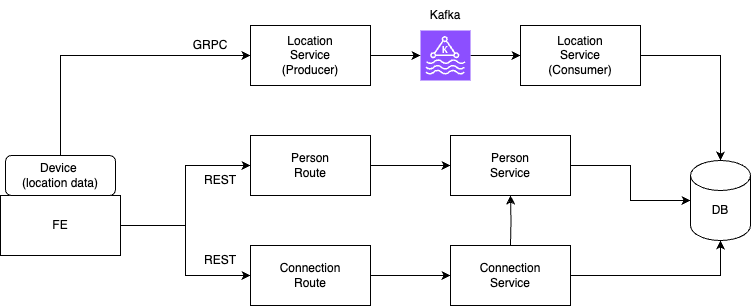
High-volume geodata ingest with gRPC and Kafka, REST reads via Flask, PostGIS proximity search, and Kubernetes on Vagrant.
View2026-08-31
High-volume geodata ingest with gRPC and Kafka, REST reads via Flask, PostGIS proximity search, and Kubernetes on Vagrant.

2026-07-05
smolagents multi-agent walkthrough — ToolCallingAgent specialists, tool trust boundaries, structured JSON handoffs, and sql db storage on a paper supply order pipeline
View2026-07-05
smolagents multi-agent walkthrough — ToolCallingAgent specialists, tool trust boundaries, structured JSON handoffs, and sql db storage on a paper supply order pipeline

2026-06-27
Orchestrating multiple agents to complete tasks involving handling customer inquiries, checking inventory status, providing accurate quotations, and completing transactions seamlessly
View2026-06-27
Orchestrating multiple agents to complete tasks involving handling customer inquiries, checking inventory status, providing accurate quotations, and completing transactions seamlessly

2026-05-24
Modeled Yelp reviews and GHCN-D climate data in a layered Snowflake warehouse from staging through ODS to star schema.
View2026-05-24
Modeled Yelp reviews and GHCN-D climate data in a layered Snowflake warehouse from staging through ODS to star schema.
Data Platforms (Kafka, Spark, Streaming)
Cloud Architecture (AWS, GCP, scalable systems)
AI Systems (RAG, Agents, LLM workflows)
Performance Engineering (low latency systems)
5B+ rows processed daily
50% faster data processing
5 days → 13 min ML retraining
98% NLP insight accuracy
70% better data accessibility
85% fewer pipeline breakages


